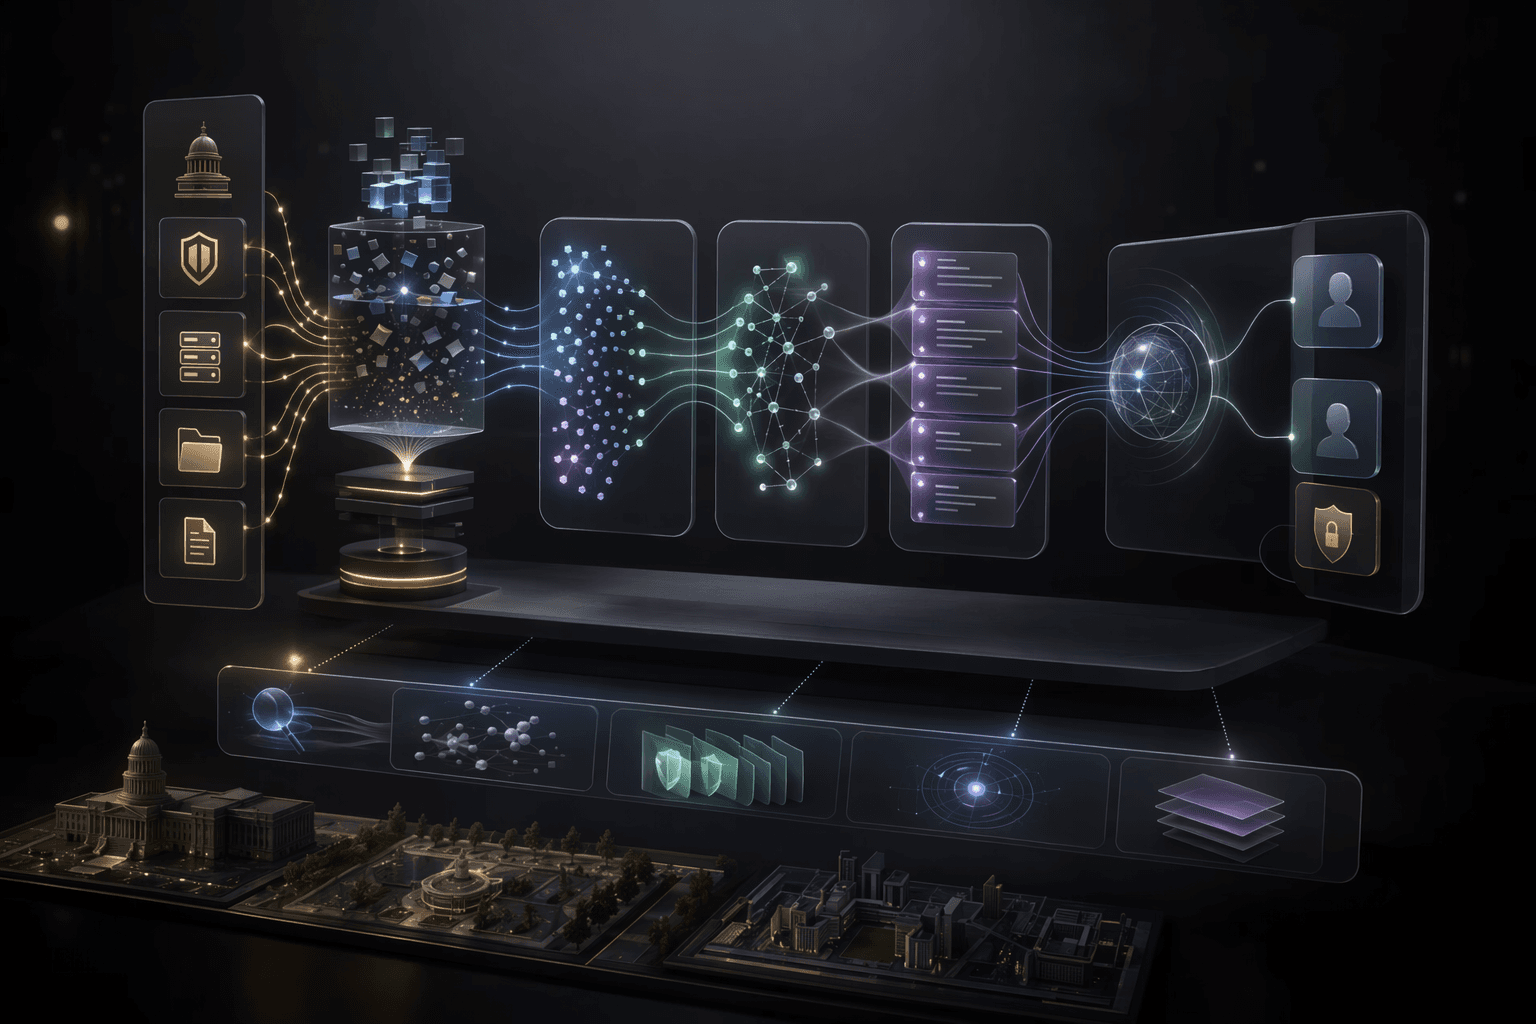
Quick answer: on-prem or private RAG is appropriate when source documents, embeddings, prompts, logs, user identities, or generated outputs must stay inside controlled infrastructure. It requires explicit data-flow mapping, deployment boundaries, model access decisions, retrieval and index ownership, permission enforcement, monitoring, patching, backups, evaluation, and audit controls. It is not just a hosting toggle.
For government RAG assistants, sovereign RAG programs, and secure enterprise RAG, the deployment choice affects document preparation, metadata strategy, hybrid retrieval, reranking, grounded generation, citations, refusal behavior, SSO, logs, telemetry, disaster recovery, and ownership after launch.
Cloud-managed knowledge-base products, enterprise search platforms, RAG frameworks, private endpoints, VPC deployments, on-prem systems, and fully air-gapped environments are different categories. The right pattern depends on data residency, procurement, latency, cost, quality, and operations constraints.
- every data surface
- Map
- Source files, chunks, embeddings, indexes, prompts, outputs, logs, backups, telemetry, and identities need defined boundaries.
- silent egress
- Zero
- Sensitive deployments need clear rules for what can leave the environment, which endpoint receives it, and who approved it.
- accountable owner
- One
- After launch, a named team must own uptime, patching, index updates, quality review, backups, and incident response.
Core idea
Private RAG succeeds when data movement, retrieval, model access, permissions, evaluation, audit, and operations are designed as one governed system.
RAG Development Company
Enterprise retrieval, hybrid search, grounding, evaluation, observability, and secure deployment.
18 Hidden RAG Mistakes
A deeper production guide to the failure modes that appear after a clean RAG demo.
MOSD Oman Policy Assistant
A multilingual government RAG assistant with accessibility support and on-prem deployment.
Extramarks Teaching Deck
An education RAG and generation workflow grounded in curriculum content.
Deployment Choice
Decide whether the system belongs in managed cloud, private cloud, hybrid, on-prem, sovereign, or air-gapped infrastructure.
6 patterns
Permission Enforcement
SSO, roles, ACLs, index-time filters, query-time filters, logs, dashboards, and admin tools need aligned access rules.
7 controls
Lifecycle Ownership
Private RAG needs patching, model and index updates, evaluation data, monitoring, incident response, and disaster recovery.
6 ops needs
Planning Decisions
Decisions Before Choosing Private RAG
On-prem deployment should be chosen for a specific data, security, procurement, or operations reason. Once chosen, it affects the entire RAG lifecycle.
MythyaVerse treats this as production RAG work: document preparation, metadata strategy, hybrid retrieval, reranking, grounded generation, multilingual behavior, evaluation, monitoring, and secure cloud, hybrid, or on-prem deployment constraints.
Choose private, cloud-managed, or hybrid deliberately
- Decision
- A government or enterprise team may choose cloud-managed RAG, private cloud, VPC, hybrid, on-prem, sovereign, or air-gapped deployment depending on where data and operations are allowed to live.
- Why it matters
- Managed cloud services can reduce infrastructure work when policy allows them, but they are not automatically a fit for source data, embeddings, prompts, logs, or outputs that must remain inside controlled infrastructure.
- Practical move
- Compare patterns against data residency, procurement review, integration limits, latency, cost, answer quality, staffing, and audit obligations before selecting the deployment model.
Map every data surface
- Decision
- Source files, parsed text, chunks, embeddings, indexes, prompts, chat history, generated outputs, logs, backups, telemetry, and user identities can each have different sensitivity levels.
- Why it matters
- A system can satisfy document residency while accidentally exposing prompts, logs, analytics events, evaluation records, or backup copies if the boundary is incomplete.
- Practical move
- Create a data-flow map that shows where each surface is created, stored, transformed, transmitted, retained, backed up, monitored, and deleted.
Decide model access and generation boundaries
- Decision
- Some deployments use local models, some use private endpoints, some call approved managed endpoints, and some use separate models for rewriting, embedding, reranking, generation, and evaluation.
- Why it matters
- Model access affects data egress, accuracy, latency, cost, hardware requirements, patching, refusal behavior, and whether an air-gapped deployment is realistic.
- Practical move
- Document which model endpoints can receive which fields, whether local models are required, how prompts are constrained, and how generated answers are cited, refused, logged, and reviewed.
Own the retrieval and index layer
- Decision
- Private RAG depends on approved source ingestion, parsing, chunking, metadata, embeddings, vector or hybrid indexes, reranking, freshness rules, and index rebuilds.
- Why it matters
- If the organization owns the deployment but not the retrieval lifecycle, the assistant can become stale, over-permissive, hard to debug, or expensive to maintain.
- Practical move
- Assign owners for source approval, metadata policy, embedding strategy, index-time permission fields, query-time filters, hybrid retrieval, reranking, index updates, backups, and rollback.
Enforce permissions from SSO to retrieval
- Decision
- SSO, roles, groups, document ACLs, workspace permissions, admin rights, reviewer queues, logs, and dashboards should follow the same access model.
- Why it matters
- A user should not get an answer from a document they cannot read, and an operator should not see sensitive prompts or outputs unless their role allows it.
- Practical move
- Use SSO and role mapping, carry ACL metadata into the index, apply index-time and query-time permission filters, and test denied, mixed-permission, and escalation cases.
Monitor without leaking sensitive data
- Decision
- Production monitoring needs retrieval traces, latency, errors, unresolved intents, citation support, refusal rates, and quality review outcomes without turning analytics into a data leak.
- Why it matters
- Logs can become a second sensitive dataset because they may contain prompts, generated answers, source snippets, user identities, and operational details.
- Practical move
- Define redaction, sampling, retention, access controls, audit events, secure dashboards, and alerting rules before launch. Track enough to debug quality without copying sensitive content into unmanaged tools.
Plan lifecycle, incidents, and recovery
- Decision
- Private RAG needs security patching, model updates, embedding and index migrations, evaluation datasets, regression tests, incident response, backups, disaster recovery, and support ownership.
- Why it matters
- A secure deployment can still fail if updates break retrieval, a source system changes schema, backups are unusable, or no one owns an incident after business hours.
- Practical move
- Create runbooks for patching, content refresh, model and index updates, rollback, incident response, disaster recovery, access review, and post-incident evaluation.
Make tradeoffs explicit
- Decision
- On-prem and air-gapped RAG may improve control but can increase hardware needs, patching work, deployment friction, model limitations, and operational cost.
- Why it matters
- The private option is not automatically better for every workload. Teams still need acceptable latency, answer quality, evidence coverage, uptime, and maintainability.
- Practical move
- Compare latency, cost, quality, compliance review, staffing, procurement, support model, and ownership after launch with the same seriousness as model benchmarks.
Operating Model
Operating Model for Private RAG
The architecture should make data movement explicit, enforce permissions at retrieval time, and minimize unnecessary exposure across source systems, indexes, model calls, logs, and monitoring.
Managed RAG services, search platforms, vector databases, frameworks, and sovereign AI platforms can be evaluated as alternatives or components, but the deployment boundary still has to be proven against the organization's data policy.
Data-flow and boundary design
Map source systems, documents, parsed text, embeddings, indexes, prompts, outputs, logs, backups, telemetry, user identities, and model endpoints before implementation.
- Where it helps
- Prevents hidden data movement and makes residency, audit, retention, and deletion responsibilities concrete.
Controlled document preparation
Import approved files, parse and clean them, preserve exact identifiers, attach ownership and permission metadata, version sources, and reject stale or unapproved material.
- Where it helps
- Keeps the assistant grounded in trusted sources instead of copying every document into a private but ungoverned index.
Permission-aware retrieval
Store chunks, embeddings, lexical indexes, metadata, ACLs, and reranking signals inside the approved environment, then apply index-time and query-time permission filters.
- Where it helps
- Helps the system answer only from sources the user is allowed to access while still handling exact IDs, domain terms, follow-ups, and multilingual phrasing.
Model and generation control
Route rewriting, embedding, reranking, generation, and evaluation through approved local models, private endpoints, or managed endpoints with documented payload rules.
- Where it helps
- Reduces uncontrolled egress and makes citations, refusal behavior, prompt templates, and generated outputs reviewable.
Secure monitoring and audit
Track quality, latency, retrieval misses, citation support, refusal behavior, access events, and failures with redaction, retention, and role-based dashboard access.
- Where it helps
- Supports debugging and audit without copying sensitive prompts, source snippets, or user identities into unmanaged observability tools.
Evaluation and change control
Maintain golden queries, permission tests, multilingual examples, exact-identifier cases, no-answer cases, and regression checks for model, index, document, and prompt updates.
- Where it helps
- Shows whether a patch, source update, embedding change, or reranking adjustment improved the system or broke trusted behavior.
Operations and recovery
Define owners for uptime, patching, backups, disaster recovery, access reviews, incident response, source refreshes, and support after launch.
- Where it helps
- Turns a private RAG deployment into an operated enterprise service instead of a one-time installation.
Implementation checks
- Review whether embeddings, reranker inputs, prompts, chat history, citations, generated answers, and evaluation examples are sensitive under the organization's policy.
- Treat managed cloud RAG services, enterprise search platforms, vector databases, RAG frameworks, and sovereign AI platforms as implementation categories to evaluate, not endorsements or proof of compliance.
- Examples of categories to evaluate include AWS Bedrock Knowledge Bases, Google Agent Search, Azure AI Search, Elastic, deepset or Haystack, LangChain, LlamaIndex, and vector or hybrid search infrastructure; verify current deployment, residency, connector, and support scope directly.
- For air-gapped RAG, plan offline model packaging, document ingestion, dependency updates, vulnerability scanning, patch distribution, evaluation review, license handling, and support workflows.
- Keep prompts, generated outputs, logs, backups, telemetry, review queues, and admin dashboards in the same data classification discussion as source files.
- Build content update, index rebuild, model update, rollback, and incident response processes before the assistant is announced to internal or public users.
- Separate security certification claims from engineering controls. A private architecture can support compliance work, but it does not guarantee any certification by itself.
Practical Checklist
On-Prem RAG Readiness Checklist
Use this checklist before approving an on-prem, private, hybrid, sovereign, or air-gapped RAG build.
Keep this in mind
- Which source documents, parsed text, chunks, embeddings, indexes, prompts, chat history, logs, outputs, backups, telemetry, and user identities must remain inside controlled infrastructure?
- Is the target pattern cloud-managed, private cloud, VPC, hybrid, on-prem, sovereign, fully air-gapped, or a phased combination?
- What data-flow map shows every system that creates, stores, transforms, transmits, backs up, monitors, or deletes RAG data?
- Which model endpoints are allowed for embedding, rewriting, reranking, generation, moderation, and evaluation, and what fields can each endpoint receive?
- If local or air-gapped models are required, who owns hardware sizing, model packaging, vulnerability scanning, updates, and quality tradeoffs?
- Who approves new source files, source updates, document removals, metadata changes, and index rebuilds?
- How are SSO, roles, groups, document ACLs, reviewer permissions, admin rights, and audit access mapped into the RAG system?
- Which permissions are enforced at index time, which are enforced at query time, and how are denied and mixed-permission queries tested?
- Does retrieval combine semantic search, exact keyword search, metadata filters, hybrid retrieval, and reranking where the corpus needs them?
- How does the assistant handle ambiguous questions, exact IDs, domain terms, follow-ups, multilingual phrasing, missing evidence, conflicts, and refusal behavior?
- Can citations and audit records show which approved source, version, snippet, and permission path supported an answer?
- What monitoring is collected without leaking sensitive prompts, source snippets, outputs, user identities, or security details?
- Who reviews evaluation datasets, golden queries, no-answer cases, permission failures, citation support, latency, unresolved intents, and user feedback?
- What is the process for security patching, model updates, embedding migrations, index rebuilds, prompt changes, rollback, and post-change regression testing?
- What backup, disaster recovery, incident response, access review, procurement, and compliance review processes are required before launch?
- Who owns uptime, content freshness, infrastructure, quality review, user support, audit response, and cost after launch?
On-prem RAG can be the right choice for sensitive government and enterprise work, but it should be treated as a governed system rather than a hosting preference.
The teams that succeed make data movement, permission enforcement, retrieval quality, model access, auditability, and operational ownership explicit before launch.
Current themes
Need help?
Building a knowledge system that has to answer from trusted sources?
We design RAG systems around retrieval quality, grounding, multilingual behavior, evaluation, and secure deployment rather than demo-only chat.
Explore RAG Development